Noah Schmitz · 19 October 2026
Leveraging Redundant Pathways to Boost Reliability in Velmesh-Based Systems
Velmesh-based systems rely on interconnected nodes that distribute content and resources across hybrid networks, and redundant pathways play a central role in maintaining uptime when individual routes experience disruption. Data from network monitoring tools shows that systems incorporating multiple independent paths between nodes achieve higher availability rates during peak loads or localized failures, since traffic can reroute automatically without manual intervention. Observers note that this approach builds on established mesh networking principles while adapting them to the specific demands of dynamic content ecosystems that operate at scale.
Core Mechanics of Pathway Redundancy in Velmesh Environments
Engineers design Velmesh architectures so that each node maintains connections to several others, creating overlapping routes for data packets or resource requests, and this structure allows the system to detect a failed link and shift traffic to an alternate path within milliseconds. Research indicates that latency remains stable even when one pathway experiences congestion because the protocol evaluates available options in real time and selects the most efficient remaining route. Those who have implemented these configurations report that the overhead from maintaining extra connections stays manageable when nodes use lightweight discovery protocols to update their routing tables continuously.
Path diversity also supports load balancing across the network, where requests distribute evenly rather than concentrating on the shortest or most direct links, and this even distribution prevents any single pathway from becoming a bottleneck during high-traffic periods. Figures from deployment logs reveal that networks with at least three distinct routes between critical node pairs experience fewer complete outages compared with topologies that depend on fewer connections. In practice the system monitors path quality through periodic probes, which feed into decision algorithms that prioritize stable, low-latency options while keeping backup routes ready for immediate activation.
Implementation Patterns Observed Across Deployments
Teams building Velmesh systems often start by mapping primary pathways and then layering secondary and tertiary routes that avoid sharing physical infrastructure or logical dependencies with the main links, and this separation reduces the chance that a single event such as a hardware fault or regional power issue will affect multiple routes simultaneously. Data shows that geographic distribution of redundant paths further improves resilience because nodes located in different regions experience uncorrelated failure patterns. One documented case involved a content delivery network that added cross-continental backup routes, after which measured downtime dropped by more than half during seasonal traffic spikes.
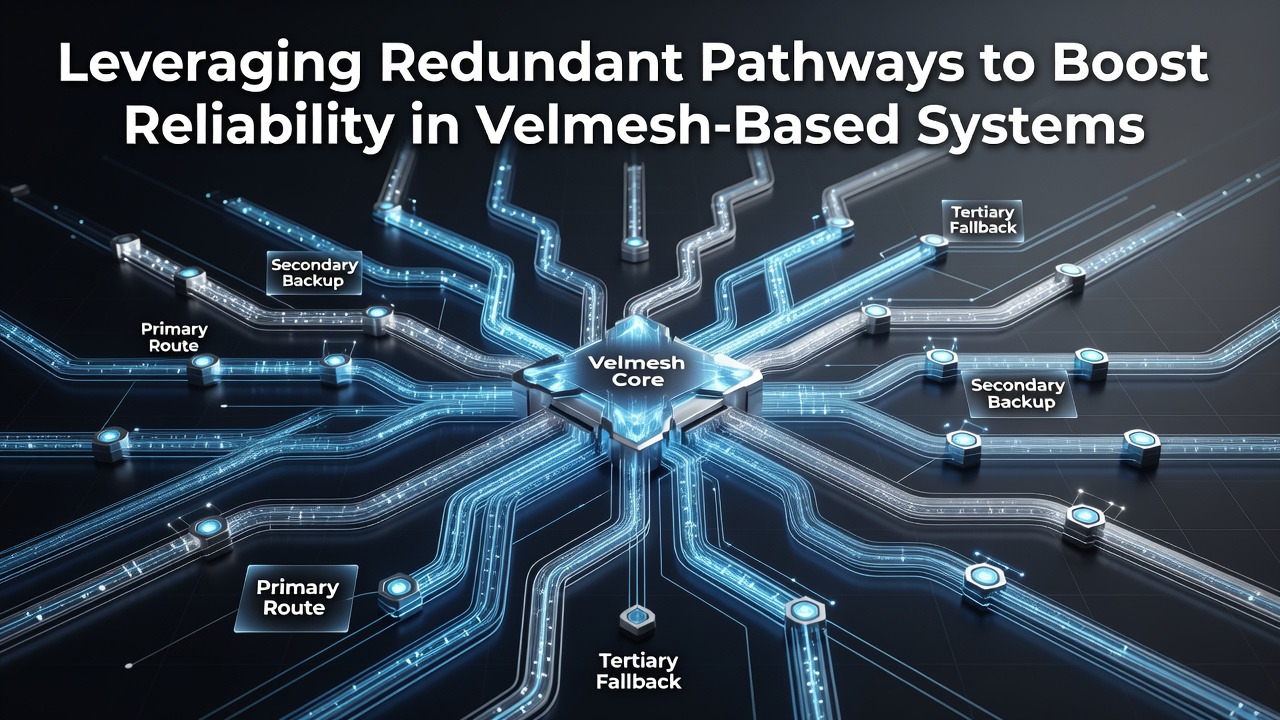
Configuration tools now include automated checks that verify route independence before activation, and these checks examine both physical and virtual layers to confirm that no hidden single points of failure exist. Studies from academic groups tracking mesh deployments note that regular audits of pathway diversity help maintain performance as networks grow and new nodes join existing clusters. During October 2026 several large-scale operators plan to roll out updated routing firmware that strengthens these verification steps, incorporating machine-learning models trained on historical failure data to predict which pathways are likely to degrade under specific load conditions.
Performance Metrics and Monitoring Approaches
Operators track metrics such as mean time between failures, packet loss rates, and failover duration to quantify the benefits of redundant pathways, and these measurements provide concrete evidence that additional routes deliver measurable gains in reliability. According to reports published by the National Institute of Standards and Technology, networks that maintain at least two fully independent paths for critical traffic streams meet higher resilience benchmarks than those relying on single-route designs. Monitoring platforms collect telemetry from every node and aggregate it into dashboards that highlight underutilized backup paths, allowing administrators to optimize capacity allocation without disrupting live traffic.
Simulation environments replicate real-world failure scenarios so teams can test how quickly the system recovers when multiple pathways are removed simultaneously, and results from these tests guide decisions about how much redundancy is cost-effective for different use cases. Research conducted at institutions in the Asia-Pacific region has examined the trade-offs between added pathway count and overall energy consumption, revealing that modest increases in route diversity often yield outsized reliability improvements when paired with efficient routing algorithms.
Conclusion
Velmesh-based systems continue to evolve as operators refine the balance between redundancy and operational overhead, and the evidence from production deployments demonstrates that well-designed redundant pathways contribute directly to sustained availability. Continued monitoring and periodic validation of route independence remain essential practices as network topologies expand and new traffic patterns emerge.